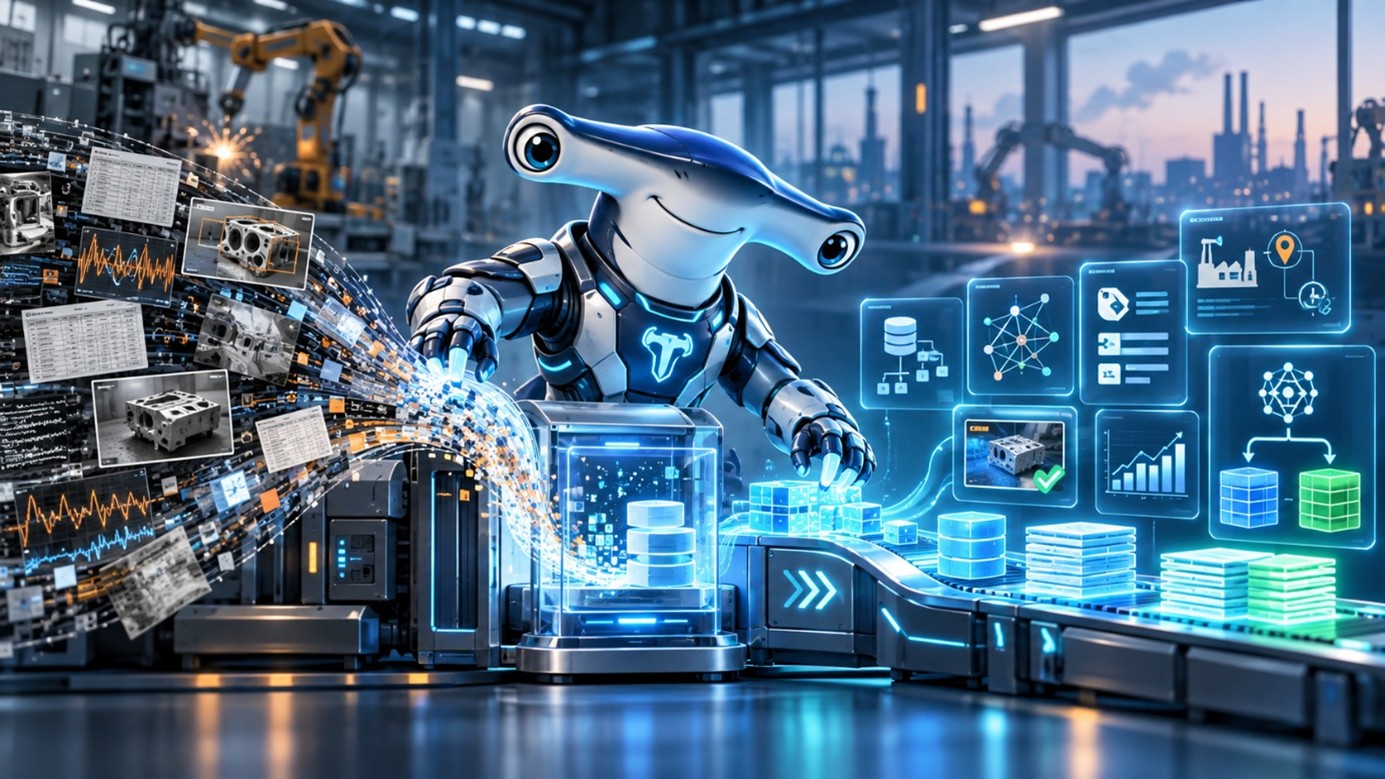
HammerHAI AI-Ready Data Engineering helps companies and research projects transform existing datasets into high-quality, AI-ready data. Using secure, AI-powered pipelines specifically tailored to manufacturing and engineering data, the service improves metadata quality, enriches semantic descriptions, and automatically prepares datasets for machine learning applications.
Target users
- Manufacturing and engineering companies that seek to improve the quality, usability, and AI readiness of their existing datasets
- Research and innovation projects that require standardized metadata and reproducible data preparation
- AI developers and data scientists looking to automate data pre-processing and assess the suitability of the dataset for machine learning tasks
- Data stewards responsible for metadata quality, interoperability, and data documentation
Description
Preparing data for AI applications often requires substantial manual effort. Industrial datasets may lack meaningful metadata, contain inconsistent structures, or require extensive preprocessing before they can be used for machine learning. Poor metadata quality also makes data sets difficult to discover, understand, and reuse.
HammerHAI AI-Ready Data Engineering addresses these challenges through automated, agentic data processing pipelines. At its core is the Agentic Data Engineer, developed at the Karlsruhe Institute of Technology, which uses AI agents to analyze datasets, identify suitable pre-processing steps, and generate reproducible, machine-learning-ready outputs.
The pipelines are specifically tailored to manufacturing and engineering applications, reflecting HammerHAI’s focus on industrial AI. They address the characteristics of industrial data, including machine and sensor measurements, production records, and quality control data, to facilitate their use in predictive maintenance, defect detection, and other engineering applications.
HammerHAI AI-Ready Data Engineering places a particular focus on metadata quality and semantic interoperability and provenance. The service complements HammerHAI Data Management by validating and enriching dataset descriptions using standards such as DCAT. This helps to make datasets more discoverable, understandable, and reusable across projects and platforms.
Beyond metadata enrichment, pipelines analyze datasets for suitability for different AI prediction tasks, generate reusable data transformations, and create appropriate training and test splits while considering potential data leakage. The resulting datasets are documented using the MLCommons Croissant format, including machine-readable metadata and provenance information.
The service supports the processing of private datasets in controlled environments. Agentic workflows can use SAIA LLM services and execute data transformations in restricted sandboxes, limiting access to sensitive information, and reducing risks from prompt injection or unauthorised data access. Structured metadata, provenance tracking, and reproducible workflows also contribute to AI governance and data management practices relevant to ISO/IEC 42001.
HammerHAI AI-Ready Data Engineeringoffers the following capabilities:
Metadata quality and semantic enrichment
- Analyze and improve the completeness, consistency, and quality of data set metadata.
- Generate standardized semantic descriptions using DCAT/DCAT-AP.
- Connect AI-ready datasets with the HammerHAI data management service.
Automated data preparation
- Identify suitable AI tasks and assess the fitness for machine learning, particularly for manufacturing and engineering applications.
- Generate pre-processing pipelines and reusable data parsers tailored to industrial datasets.
- Create training and test datasets with leak-aware splitting strategies.
- Export ML-ready datasets with Croissant metadata and provenance information.
Secure agentic processing of raw data
- Process private data sets on-premises within restricted execution environments.
- Use SAIA-LLM API powered AI agents for automated analysis and transformation.
- Apply sandbox isolation locally and controlled access to protect sensitive data on-premises and reduce prompt injection risks.
- Document processing steps to support reproducibility, auditing, and AI governance.
How it works
HammerHAI provides agentic data engineering pipelines that you can run on premises using HammerHAI LLM inference. The pipelines have been optimized for manufacturing and engineering data. We provide technical support in adapting them to project-specific requirements.
1. Access and analysis
- Select data sets from data lakes or data catalogues.
- Inspect data structures, metadata quality, and potential industrial AI applications.
2. Agentic data engineering
- Automatically identify suitable preprocessing and transformation steps.
- Generate reusable parsers and leakage-aware training/test splits.
- Execute transformations in a restricted processing environment.
3. Validation and metadata generation
- Validate the generated datasets and assess their suitability for AI tasks.
- Create standardized metadata using DCAT and MLCommons Croissant.
- Document data provenance and processing steps.
4. AI-ready results
- Provide prepared data sets and reusable transformation pipelines.
- Support integration with HammerHAI Data Management for documentation and reuse.
Applications
The service is particularly valuable for manufacturing and engineering organizations with existing datasets that are not yet suitable for AI development.
Typical use cases include:
- Industrial AI data readiness: Transform raw machine, sensor, production, and quality data into structured, documented datasets suitable for machine learning.
- Metadata quality improvement: Enrich incomplete metadata to improve data discovery, interoperability, and reuse.
- Automated ML preparation: Reduce manual effort in preprocessing, task identification, and training/test data preparation.
- Dataset suitability assessment: Evaluate whether existing industrial data sets support prediction tasks such as predictive maintenance or quality forecasting.
- Reproducible AI workflows: Document data transformations, provenance, and dataset structures using machine-readable standards.
How to get access
AI-Ready Data Engineering is under development and is offered to companies and research projects on a best-effort basis. Availability depends on the characteristics of the dataset and the required processing capabilities.
Via Email: Please contact access@hammerhai.eu with a brief description of your datasets and the intended AI application.
Service provided by

Contact
Funding
The service is supported by HammerHAI (European High-Performance Computing Joint Undertaking, Grant No. 101234027).
Disclaimer
Automated data preparation and metadata generation require expert validation. The results depend on the quality and characteristics of the input data and might contain AI hallucinations.
Security measures are designed to support practices aligned with ISO/IEC 27001, while data documentation and traceability can support AI governance under ISO/IEC 42001. These capabilities do not themselves establish certification or guarantee compliance with either standard.